Research
I study how agents fail, where decision models help, and how to build dependable 3D systems. These experiments connect measured results to the larger problems I’m working on.
Agent evaluation · Handshake AI
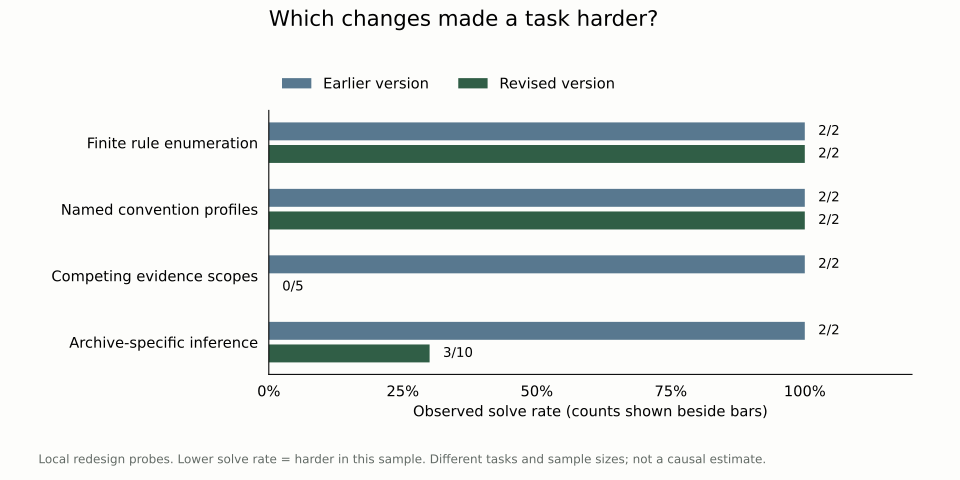
Comparing ways to challenge coding agents: finite rules, competing evidence, scope boundaries, and archive-specific inference.
Finite rule and convention tasks stayed at 2/2 solved in the selected local probes. Scope-conflict and archive-inference revisions reduced observed solves to 0/5 and 3/10.
Agent evaluation
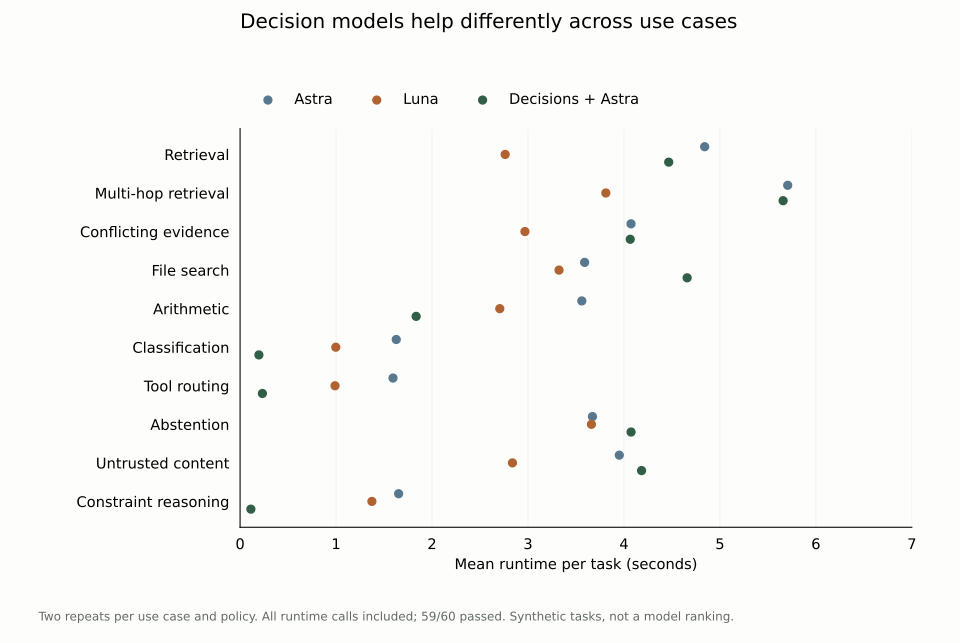
Comparing general LLMs and a decision-model hybrid across retrieval, tool routing, arithmetic, classification, and other tasks.
In a 60-run synthetic benchmark, Decisions + Astra completed 20/20 tasks at 22% lower estimated cost than Astra. Gains concentrated in bounded choices; many file-based tasks still needed Astra.
Computational geometry
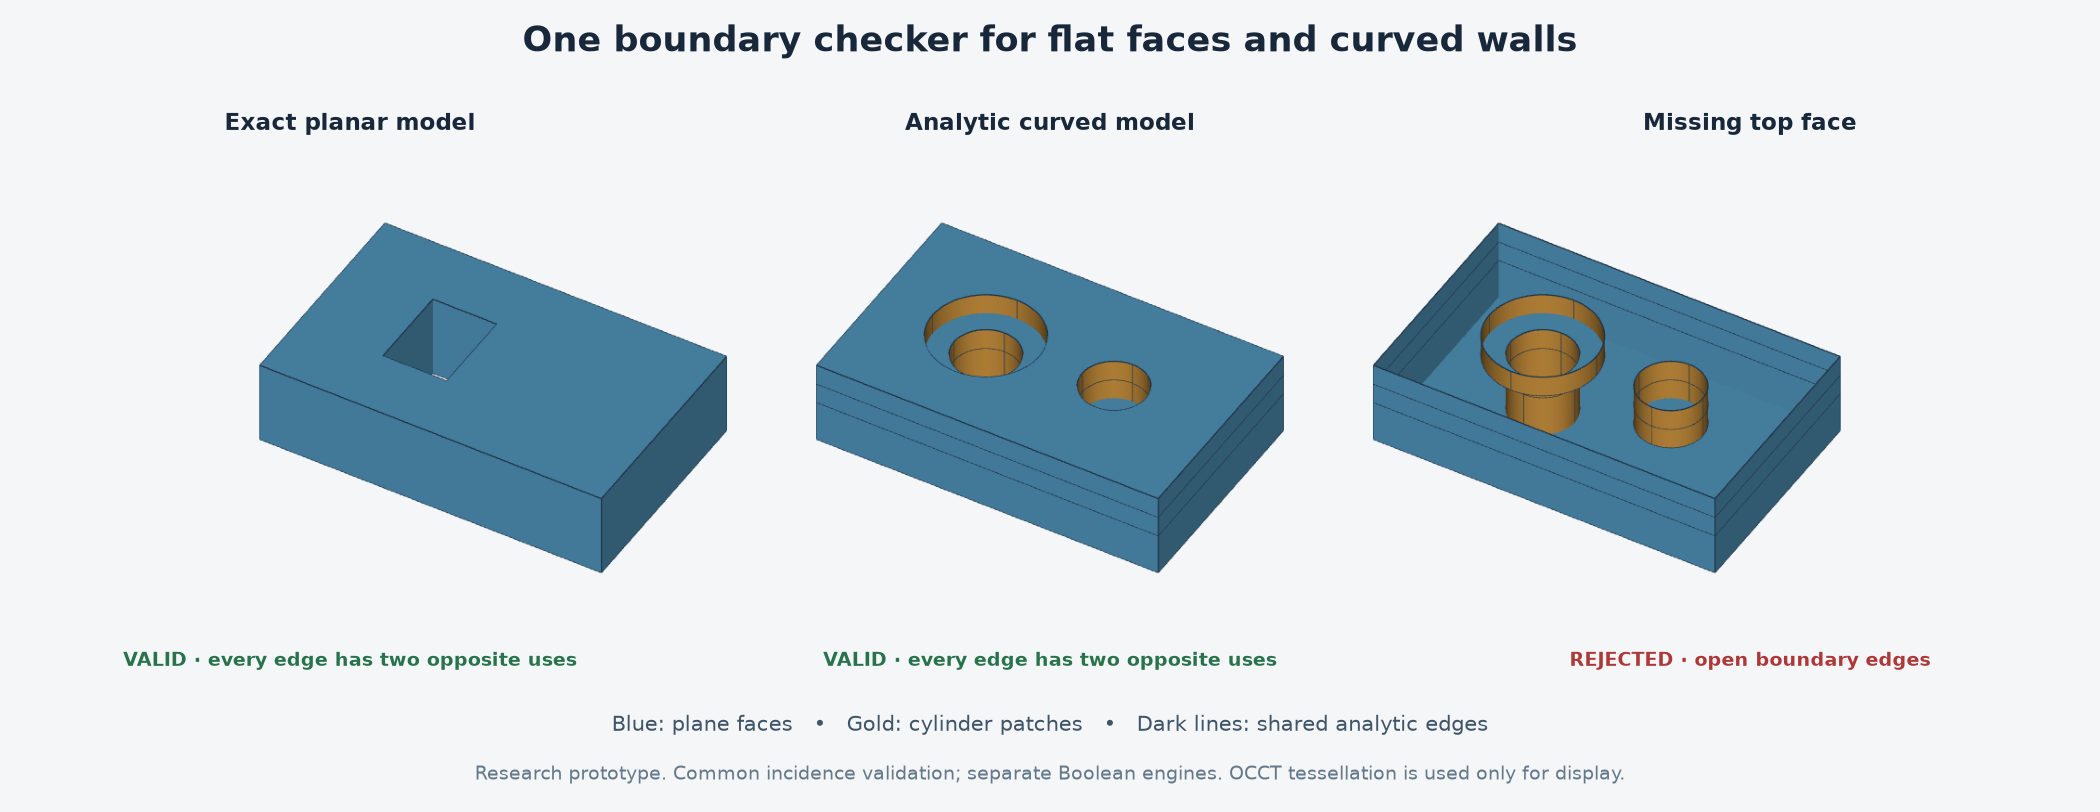
Comparing an original boundary representation with an independent geometry engine.
54 OCCT comparisons passed. Maximum volume difference: 2.73 × 10⁻¹² mm³ across the tested cases.
3D representation
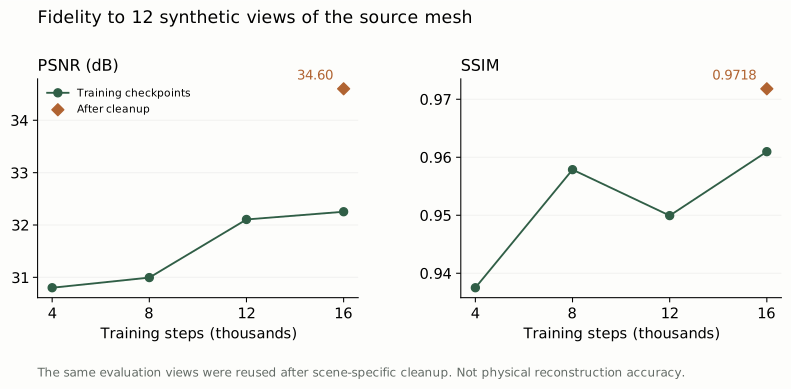
Measuring how well a trained splat reproduces synthetic views of an apartment mesh.
After scene-specific cleanup: 34.60 dB PSNR and 0.9718 SSIM on the same 12 synthetic evaluation views.
Computer vision
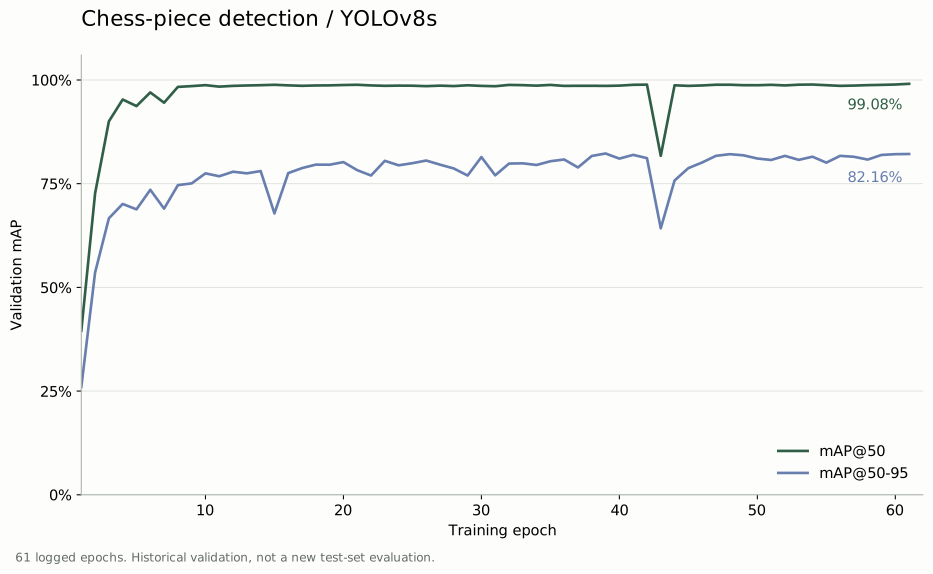
Fine-tuning YOLOv8s and connecting piece detections to a structured board state.
61 logged epochs. Final validation mAP@50-95: 82.16%; no physical-gameplay claim.